Projects & Publications
Engineering
Large systems I led as engineer.
-
-
Hermes
Large-scale applications such as simulation, deep learning, and data analytics produce and analyze massive volumes of data. These data movements are typically the main bottleneck of these applications. To reduce the gap between computation and storage, HPC and Cloud sites have integrated fast tiers of storage, known as the Deep Memory and Storage Hierarchy (DMSH). However, efficiently utilizing the DMSH is complex, especially when heterogeneity is considered. Hermes is a new I/O buffering platform that places, shuffles, and migrates data within the DMSH automatically. Hermes is a $4 million dollar NSF project, where I was the lead engineer and primarily responsible for the implementation, testing / debugging, and evaluation of Hermes.
Papers
Conference papers, preprints, and my dissertation.
-
VaultxGPU: GPU-Accelerated Blockchain Consensus
arXiv preprint arXiv:2606.14007
Proof-of-Space blockchains replace repeated computation with storage, but plot generation remains bottlenecked by CPU hashing throughput. VaultxGPU is a GPU-accelerated extension of the VaultX plotter that offloads the Blake3 hashing pipeline to the GPU using custom CUDA and SYCL kernels, keeping Table 1 entirely in GPU VRAM and fusing the sort and match stages into a single kernel to minimize data movement. The SYCL implementation achieves a 59.2x speedup over a single-threaded CPU baseline and outperforms even the best 384-thread CPU configuration.
-
Recombinant: A Composable, Extensible, Intelligent I/O Platform for Integrated High-Performance I/O Management
PhD Dissertation, Illinois Institute of Technology, Chicago, IL
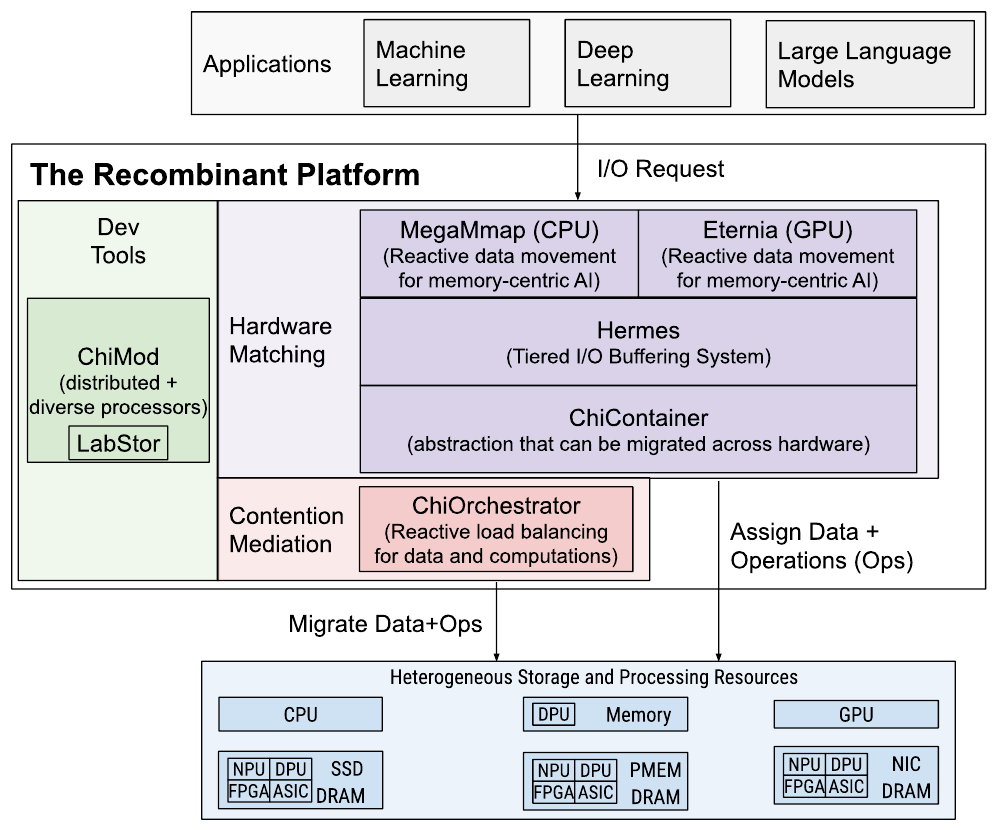
Modern data analytics, AI, and scientific simulation workloads are increasingly data-intensive, and storage systems struggle to keep up with their dynamic and conflicting I/O behaviors. Meanwhile, the explosion of storage and processing hardware has no abstraction to mask its complexity. Recombinant is a composable I/O platform that re-envisions how I/O stacks are developed, deployed, and scheduled across all integrated resources. Custom I/O features can be built and uploaded with minimal service interruption, composed into workload-specific I/O stacks, and orchestrated by intelligent policies that mediate contention. Evaluations show up to 10x fewer lines of code, 4x lower peak memory utilization, and 80x lower p99 latency.
-
DTIO: Data Stack for AI-driven Workflows
Proceedings of the 37th International Conference on Scalable Scientific Data Management (SSDBM ’25)
HPC, Big Data Analytics, and Machine Learning have become increasingly intertwined as models such as LLMs and diffusion models drive discovery in scientific fields. However, each domain has its own storage infrastructure with unique I/O interfaces and often incompatible feature sets, forcing users into expensive conversions. To better support converged HPC, Big Data, and ML workflows, this paper proposes DTIO, a scalable I/O runtime that unifies these disparate I/O stacks.
-
MegaMmap: Blurring the Boundary Between Memory and Storage for Data-Intensive Workloads
SC24: International Conference for High Performance Computing, Networking, Storage and Analysis
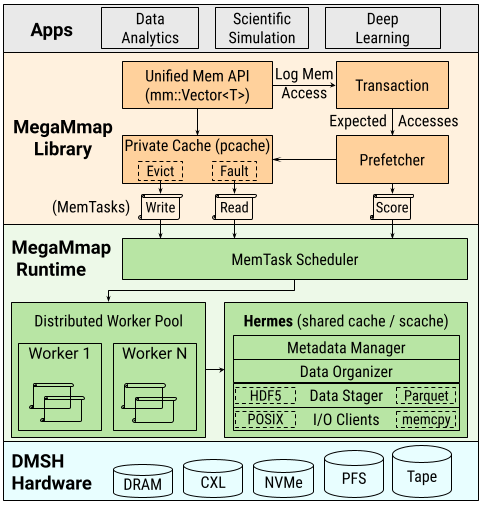
Large-scale data analytics, scientific simulation, and deep learning codes in HPC perform massive computations on data greatly exceeding the bounds of main memory. These out-of-core algorithms suffer from severe data movement penalties, programming complexity, and limited code reuse. To solve this, HPC sites have steadily increased DRAM capacity. However, this is not sustainable due to financial and environmental costs. A more elegant, low-cost, and portable solution is to expand memory to distributed multi-tiered storage. In this work, we propose MegaMmap: a software distributed shared memory (DSM) that enlarges effective memory capacity through intelligent tiered DRAM and storage management. Evaluations show that various workloads can be executed with a fraction of the DRAM while offering competitive performance.
-
Hades: A Context-Aware Active Storage Framework for Accelerating Large-Scale Data Analysis
2024 IEEE 24th International Symposium on Cluster, Cloud and Internet Computing (CCGrid ’24)
Modern simulation workflows generate and analyze massive amounts of data using I/O libraries like ADIOS2 and NetCDF. Executing analytical queries, which often require iterative traversals of large files, is cumbersome and constrained by low I/O performance. Hades is a context-aware I/O layer that actively and asynchronously computes and stores derived quantities while data is in transit, leveraging a hierarchical buffering system with data access-aware prefetching and a flexible query interface. Hades is implemented as an ADIOS2 plugin engine on top of the Hermes buffering platform.
-
LuxIO: Intelligent Resource Provisioning and Auto-Configuration for Storage Services
2022 IEEE 29th International Conference on High Performance Computing, Data, and Analytics (HiPC ’22)
HPC applications demonstrate diverse I/O requirements that can be better served by a multi-storage approach, yet the burden of provisioning and configuring intermediate storage falls solely on users. LuxIO is an intelligent storage resource provisioning and auto-configuration service that constructs storage deployments configured to best match I/O requirements. LuxIO-tuned storage services show performance improvements of up to 2x with only 93.40 ms of overhead on top of existing job scheduling pipelines, and improve resource utilization by up to 25%.
-
LabStor: A Modular and Extensible Platform for Developing High-Performance, Customized I/O Stacks in Userspace
SC22: International Conference for High Performance Computing, Networking, Storage and Analysis
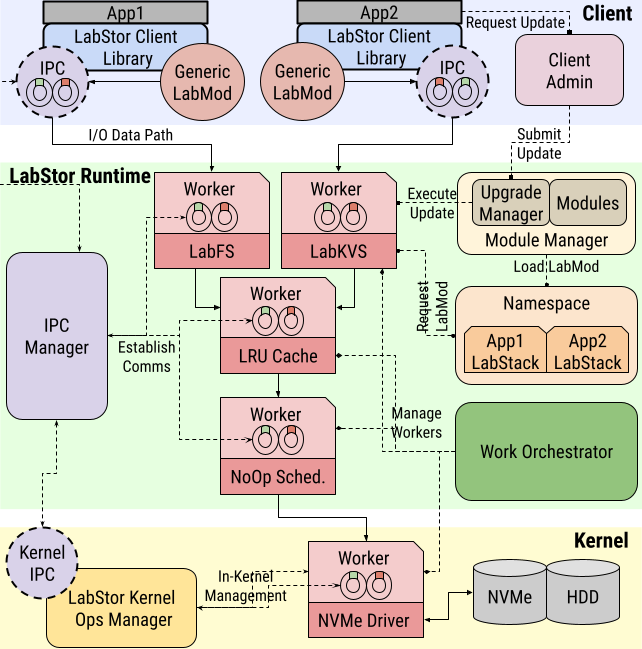
Traditionally, I/O systems have been developed within the confines of a centralized OS kernel. This led to monolithic and rigid storage systems that are limited by low development speed, expressiveness, and performance. However, this monolithic design philosophy makes it difficult to develop and deploy new I/O approaches to satisfy the rapidly-evolving I/O requirements of modern scientific applications. To this end, we propose LabStor: a modular and extensible platform for developing high-performance, customized I/O stacks. Evaluations show that by switching to a fully modular design, tailored I/O stacks can yield performance improvements of up to 60% in various applications.
-
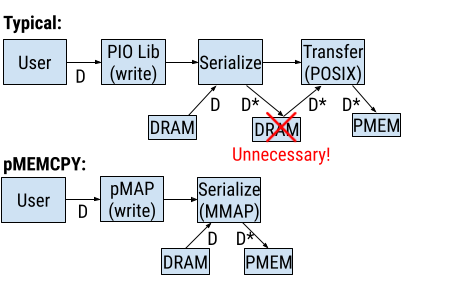
pMEMCPY: A Simple, Lightweight, and Portable I/O Library for Storing Data in Persistent Memory
2021 IEEE International Conference on Cluster Computing (CLUSTER ’21)
Persistent memory (PMEM) devices can achieve comparable performance to DRAM while providing significantly more capacity. This has made the technology compelling as an expansion to main memory. Rethinking PMEM as storage devices can offer a high performance buffering layer for HPC applications to temporarily, but safely store data. However, modern parallel I/O libraries, such as HDF5 and pNetCDF, are complicated and introduce significant software and metadata overheads when persisting data to these storage devices, wasting much of their potential. In this work, we explore the potential of PMEM as storage through pMEMCPY: a simple, lightweight, and portable I/O library for storing data in persistent memory. We demonstrate that our approach is up to 2x faster than other popular parallel I/O libraries under real workloads.
-
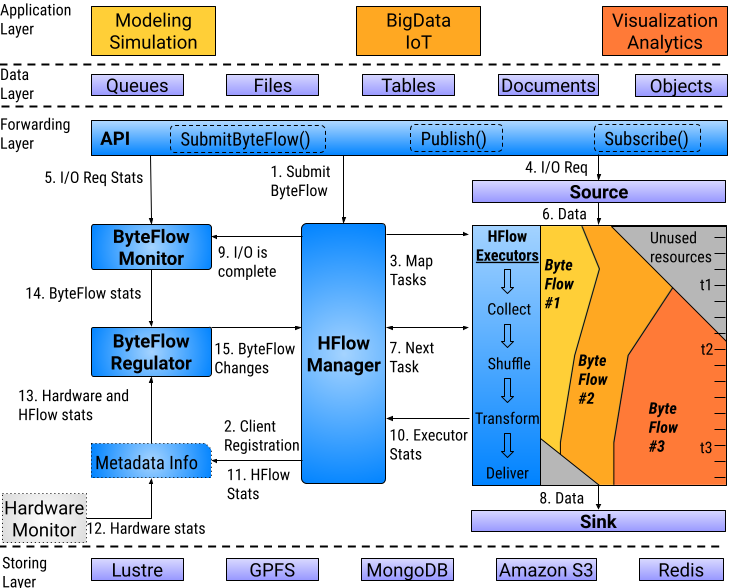
HFlow: A Dynamic and Elastic Multi-Layered I/O Forwarder
2021 IEEE International Conference on Cluster Computing (CLUSTER ’21)
To mask the I/O gap, new system architectures include intermediate I/O resources (e.g., Burst Buffers). However, the management of these resources lead to a number of concerns. They are managed in isolation, leading to inefficient interactions. Each technology manages a static set of resources, leading to load imbalance. Jobs receive exclusive access to resources, leading to resource under-utilization. Lastly, they have limited support for in-transit computations, which can reduce data movement cost. We present HFlow: a data forwarding framework that adopts a continuous data movement approach. Results show that HFlow can boost application I/O performance by up to 3x.
-
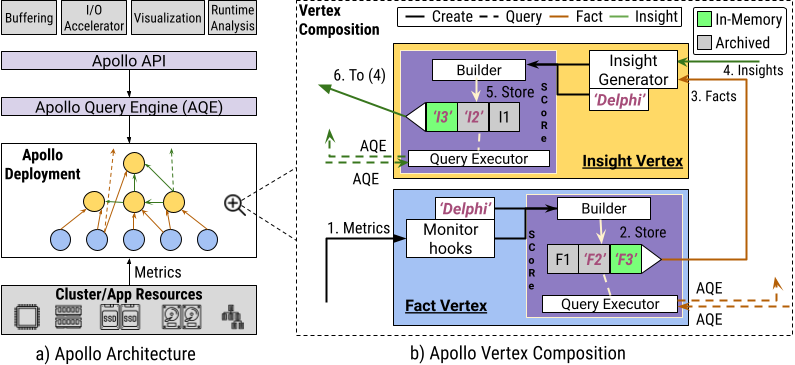
Apollo: An ML-assisted Real-Time Storage Resource Observer
Proceedings of the 30th International Symposium on High-Performance Parallel and Distributed Computing (HPDC ’21)
Middleware services require low-latency access to telemetry data in order to make optimal decisions. However, typical monitoring services store this data in databases, resulting in significant latency penalties. This work presents Apollo: a low-latency monitoring service that aims to provide applications and middleware libraries with low latency access to relational telemetry data. Apollo provides this using a Pub-Sub API and machine learning to predict changes in the data to avoid constant polling. Evaluations showcase that Apollo can achieve sub-millisecond latency for acquiring complex insights with a memory overhead of 57MB and CPU overhead being only 7% more than existing state-of-the-art systems.
-
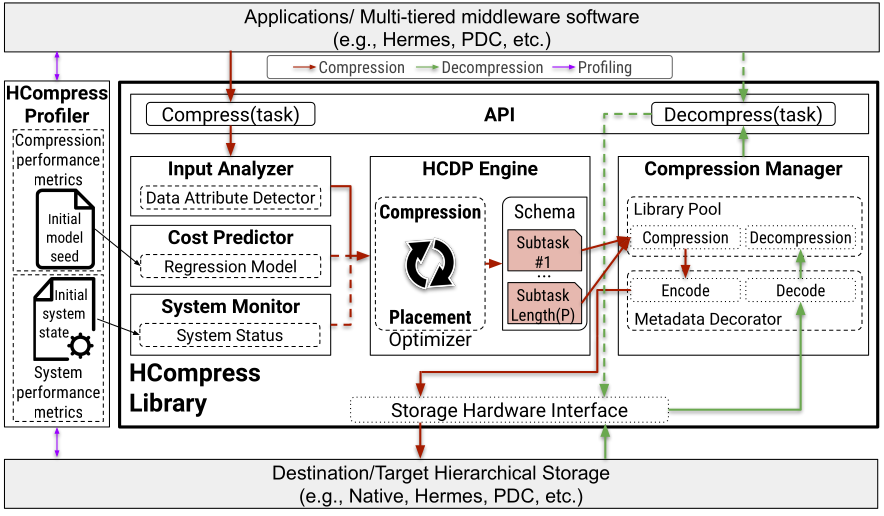
HCompress: Hierarchical Data Compression for Multi-Tiered Storage Environments
2020 IEEE International Parallel and Distributed Processing Symposium (IPDPS ’20)
Modern scientific applications are bounded by data access speeds. HCompress is a C++ library for caching data in a heterogeneous distributed environment. It employs a dynamic and adaptive compression system for matching compression libraries to different storage devices using reinforcement learning. We found that HCompress improved the performance of real-world workloads by as much as 700% relative to other modern storage solutions.
Workshops
Workshop papers and works in progress.
-
Towards AI-Driven Interfaces for Scientific Data Management
Parallel Data Systems Workshop (PDSW ’25), Work-in-Progress session, held with SC25
Exploring and producing scientific data requires researchers to navigate a complex ecosystem of disconnected tools across data gathering, resource allocation, application deployment, and data analysis. Large language models (LLMs) promise to simplify HPC tasks through natural language interfaces: instead of writing an sbatch script with multiple flags, a scientist can simply prompt "Run my simulation on 32 cores for three hours." This work explores AI-driven interfaces that bring these capabilities to scientific data management.
-
An Evaluation of DAOS for Simulation and Deep Learning HPC Workloads
Proceedings of the 3rd Workshop on Challenges and Opportunities of Efficient and Performant Storage Systems (CHEOPS ’23); also in ACM SIGOPS Operating Systems Review, 2024
Distributed storage stacks are being re-designed to take advantage of modern hardware such as PMEM and 200GbE by utilizing new hardware interfaces which bypass the OS kernel entirely. However, the impact of these optimizations has not been well-studied for real HPC workloads on real hardware. This work provides a comprehensive evaluation of DAOS, a state-of-the-art distributed storage system which re-architects the storage stack from scratch for modern hardware, and demonstrates performance improvements of up to 6x in real scientific applications. Also published in ACM SIGOPS Operating Systems Review (2024).
-
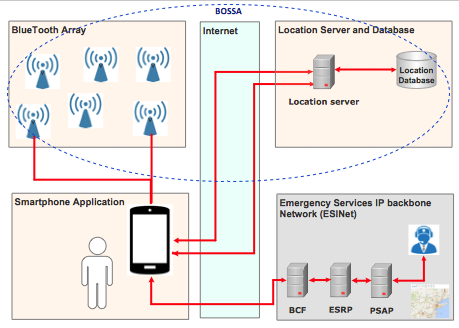
Determining the Indoor Location of an Emergency Caller in a Multi-story Building
2020 IEEE International Workshop Technical Committee on Communications Quality and Reliability (CQR ’20)
The FCC estimated that 10,000 lives could be saved annually if commercial mobile radio service (CMRS) providers were able to find the indoor location of emergency callers in a multi-story building. The BOSSA Platform is a proof-of-concept system that can find the indoor location of a cell phone using signals from Bluetooth Low Energy (BLE) beacons and a backend server for calculating indoor location based off of signal strengths. In our trials, we were able to estimate the floor the caller was on 100% of the time as well as the position on the floor to within 10 meters of accuracy.
Posters & Presentations
Posters, extended abstracts, and Sandia presentations.
-
Insights into GPUDirect Data Transfer through NIXL Benchmarking
2025 IEEE International Conference on eScience (eScience ’25)
Scientific applications are turning to GPUs to analyze and produce data due to advances in AI technologies. However, getting data to the GPU from storage is a challenge. Although technologies such as NVIDIA GDS and NIXL exist, limited research has been conducted on the actual benefits and trade-offs of these technologies. This work explores the benefits and trade-offs of using GDS and the NIXL library through benchmarking experiments.
-
Why Wait!? Hades: An Active, Content-Aware System for Precalculating Derived Quantities
SC23 Research Posters
Modern scientific applications generate vast amounts of data, typically stored as monolithic files on a parallel file system. During analysis, applications must process the entire file to derive information, which is highly inefficient due to I/O stalls. To reduce stall times, derived quantities can be pre-computed while the data is produced and then queried in the analysis phase, which requires additional capacity and intelligent use of storage.
-
A Comparative Analysis of DAOS for Simulation and Deep Learning HPC Workloads
Sandia National Laboratories, SAND2023-01820C
A comparative evaluation of DAOS, a distributed storage system re-architected from scratch for modern hardware, against traditional kernel-based storage stacks for simulation and deep learning HPC workloads, showing performance improvements of up to 6x in real scientific applications.
-
Re-architecting Storage Systems for Modern Hardware: Is It Worth It?
Sandia National Laboratories, SAND2022-11373C
Distributed storage systems have traditionally relied upon interfaces provided by the OS kernel, which impose serious overheads on every I/O operation, especially on high-performance storage and networking hardware (e.g., PMEM and 200GbE). Storage stacks are being re-designed to bypass the kernel entirely; this work examines whether the re-architecture is worth it.
-
Utilizing Persistent Memory in Parallel I/O Libraries
Scientific applications use parallel I/O libraries such as ADIOS, HDF5, and NetCDF to manage the complexity of reading and writing massive amounts of data. Multi-tiering, which uses fast storage to absorb writes, is a common and effective approach to improving I/O performance. However, parallel I/O libraries have not adequately adapted to the emergence of persistent memory (PMEM) as a new tier of storage.
-
pMEMCPY: An Efficient I/O Library for PMEM
Sandia National Laboratories, SAND2021-8666C
Persistent memory (PMEM) can achieve comparable performance to DRAM while providing significantly more capacity, making it a compelling high-performance buffering layer for HPC applications. However, parallel I/O libraries such as HDF5 and pNetCDF introduce significant software and metadata overheads when persisting data to PMEM. This work presents pMEMCPY, an efficient I/O library for storing data in PMEM.
-
Quantifying the Overheads of the Modern Linux I/O Stack
Linux is the foundation of 9 of the top 10 public clouds and all Top500 supercomputers. Distributed storage services such as object stores, parallel file systems, and databases largely rely on the Linux I/O stack, storing data using the UNIX file representation and accessing it through POSIX. The performance of the Linux I/O stack is therefore critical to these applications as a whole; this work quantifies its overheads.
Other Projects
Projects outside of systems research.
-
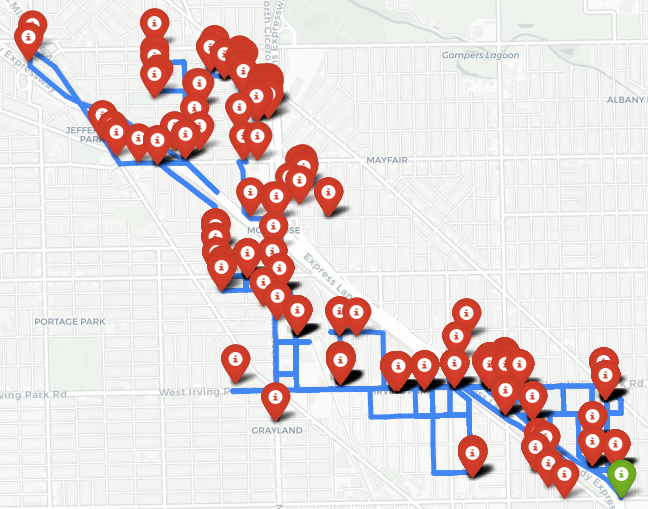
Pothole Detectives (PhDs)
Pothole damage costs US drivers $3 billion per year. In order to combat this problem, driverless pothole-filling robots will become reality. In this project, we developed a routing algorithm based off of a combination of the Chinese Postman Problem and the Traveling Salesman Problem. We used OpenStreetMap and Geopandas to obtain graphs of the wards of Chicago and used the Chicago Data Portal to get the set of active pothole reports in Chicago.
Nothing matches your search.